
Hello, I am Yiming Zhong, a master student in the Visual & Data Intelligence (VDI) Center, 4DVLab at ShanghaiTech University, supervised by Yuexin Ma and Xinge Zhu from MMLAB at The Chinese University of Hong Kong. Before that, I received my bachelor's degree from Shandong University. I'm interested in computer vision, machine learning, and their applications in robotics, particularly in embodied AI and vision-language-action models. If you have any questions, feel free to drop me an email!
📝 Publications
* Indicates Equal Contribution † Indicates Corresponding Author ‡ Indicates Project Lead
World & Action Modeling
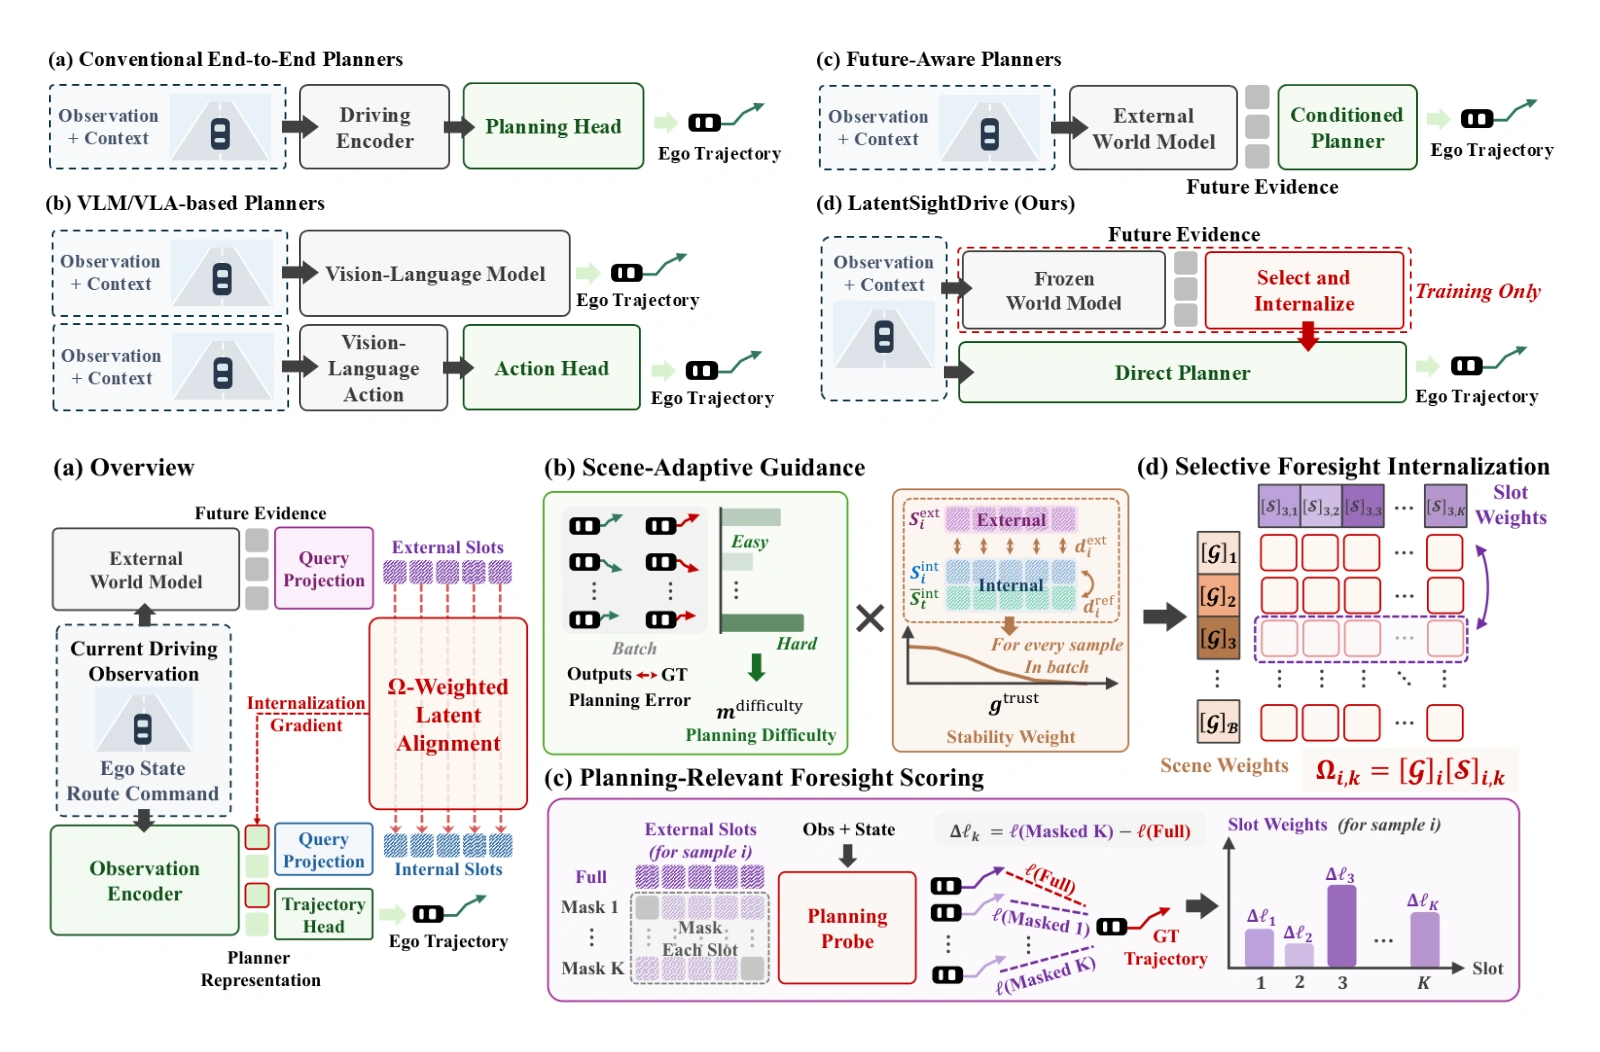
LatentSightDrive: Progressive Foresight Internalization for Autonomous Driving
Xue Zhao, Yiming Zhong, Zemin Yang, Xiang Feng, Jin Pan, Xinbing Wang, Xinge Zhu, Yuexin Ma†, Nanyang Ye†
We introduce LatentSightDrive, a framework that internalizes future evidence from an external world model for autonomous driving. Scene-adaptive guidance and planning-relevant foresight scoring selectively align internal and external latent representations to support trajectory planning.
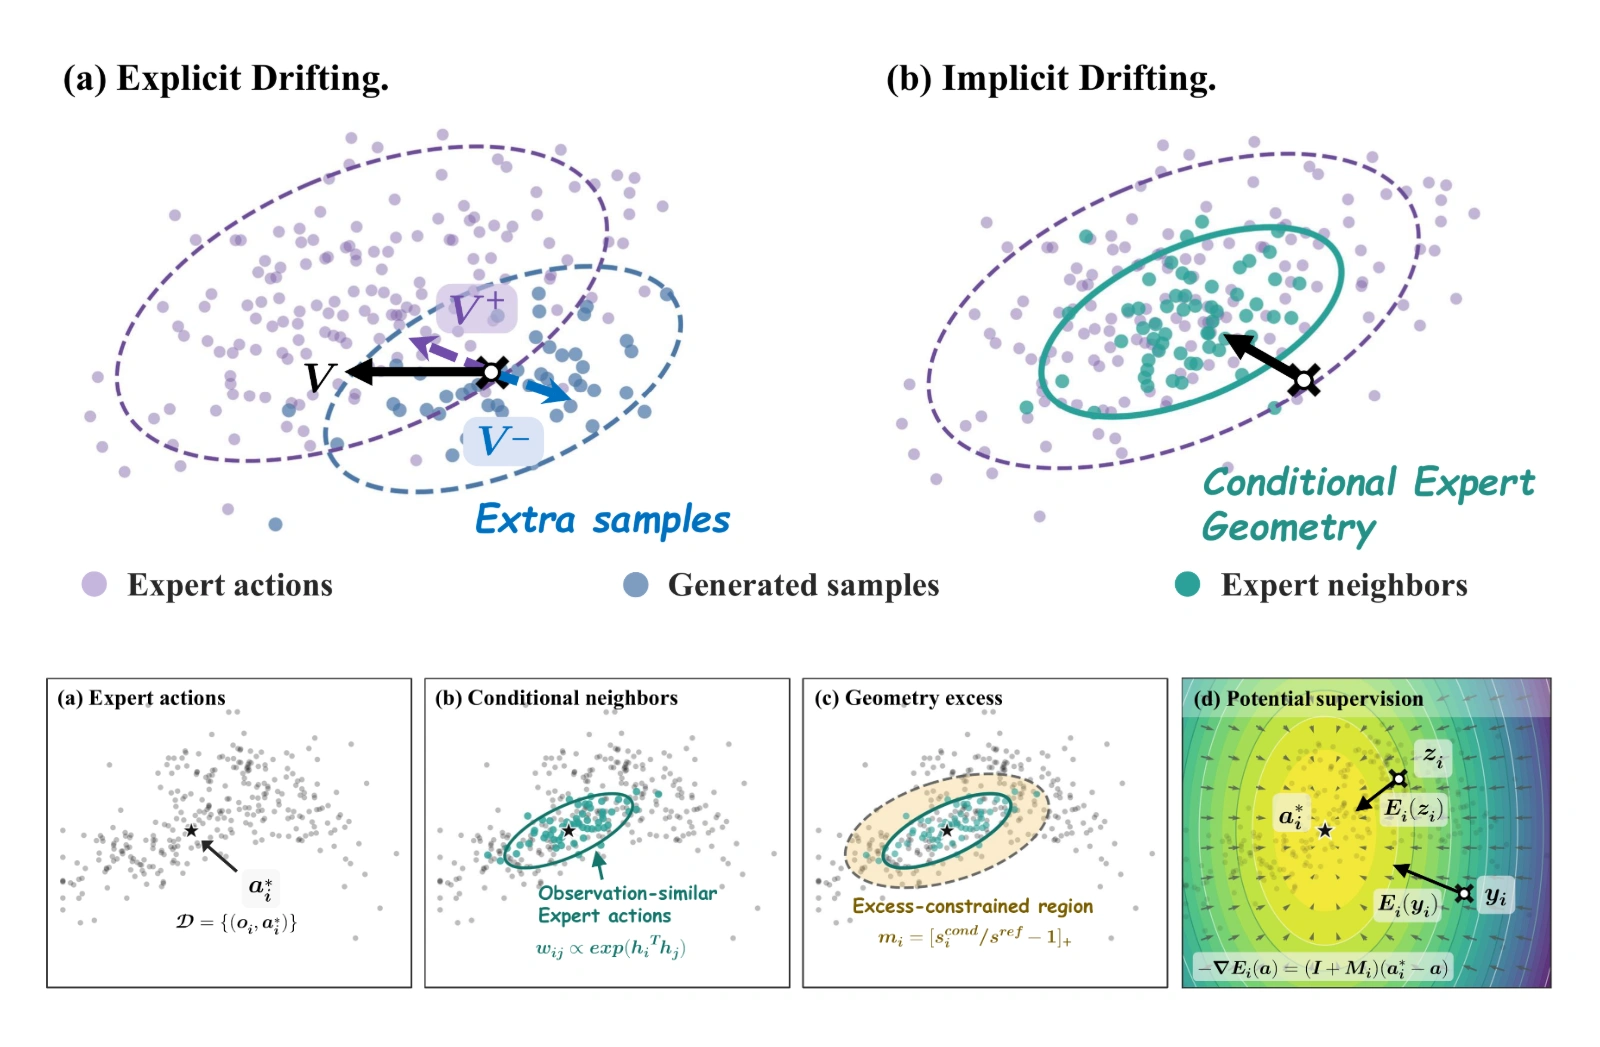
Implicit Drifting Policy: One-Step Action Generation via Conditional Expert Geometry
Zemin Yang, Yaoyu He, Yiming Zhong, Yuhao Zhang, Xinge Zhu, Yao Mu, Qingqiu Huang, Yuexin Ma†
We introduce Implicit Drifting Policy, a one-step imitation learning framework that uses conditional expert geometry to guide policy training without explicit vector field estimation. It combines efficient action generation with geometric constraints, achieving competitive performance across 2D, 3D, and real-world manipulation tasks.
PDF Project page
ResVLA: From Noise to Intent: Anchoring Generative VLA Policies with Residual Bridges
Yiming Zhong*, Yaoyu He*, Zemin Yang*, Pengfei Tian, Yifan Huang, Qingqiu Huang, Xinge Zhu, Yuexin Ma†
We introduce ResVLA, a generative vision-language-action framework that shifts robot control from generation-from-noise to refinement-from-intent by anchoring low-frequency semantic intent and refining high-frequency residual dynamics, achieving strong robustness, faster convergence, and competitive performance.
PDF Project page Github
FreqPolicy: Frequency Autoregressive Visuomotor Policy with Continuous Tokens
Yiming Zhong, Yumeng Liu, Chuyang Xiao, Zemin Yang, Youzhuo Wang, Yufei Zhu, Ye Shi, Yujing Sun, Xinge Zhu, Yuexin Ma†
This paper proposes FreqPolicy, a frequency-domain autoregressive visuomotor policy that progressively models hierarchical frequency components with continuous latent representations, achieving superior accuracy and efficiency in robotic manipulation tasks.
PDF Page GithubDexterous Manipulation
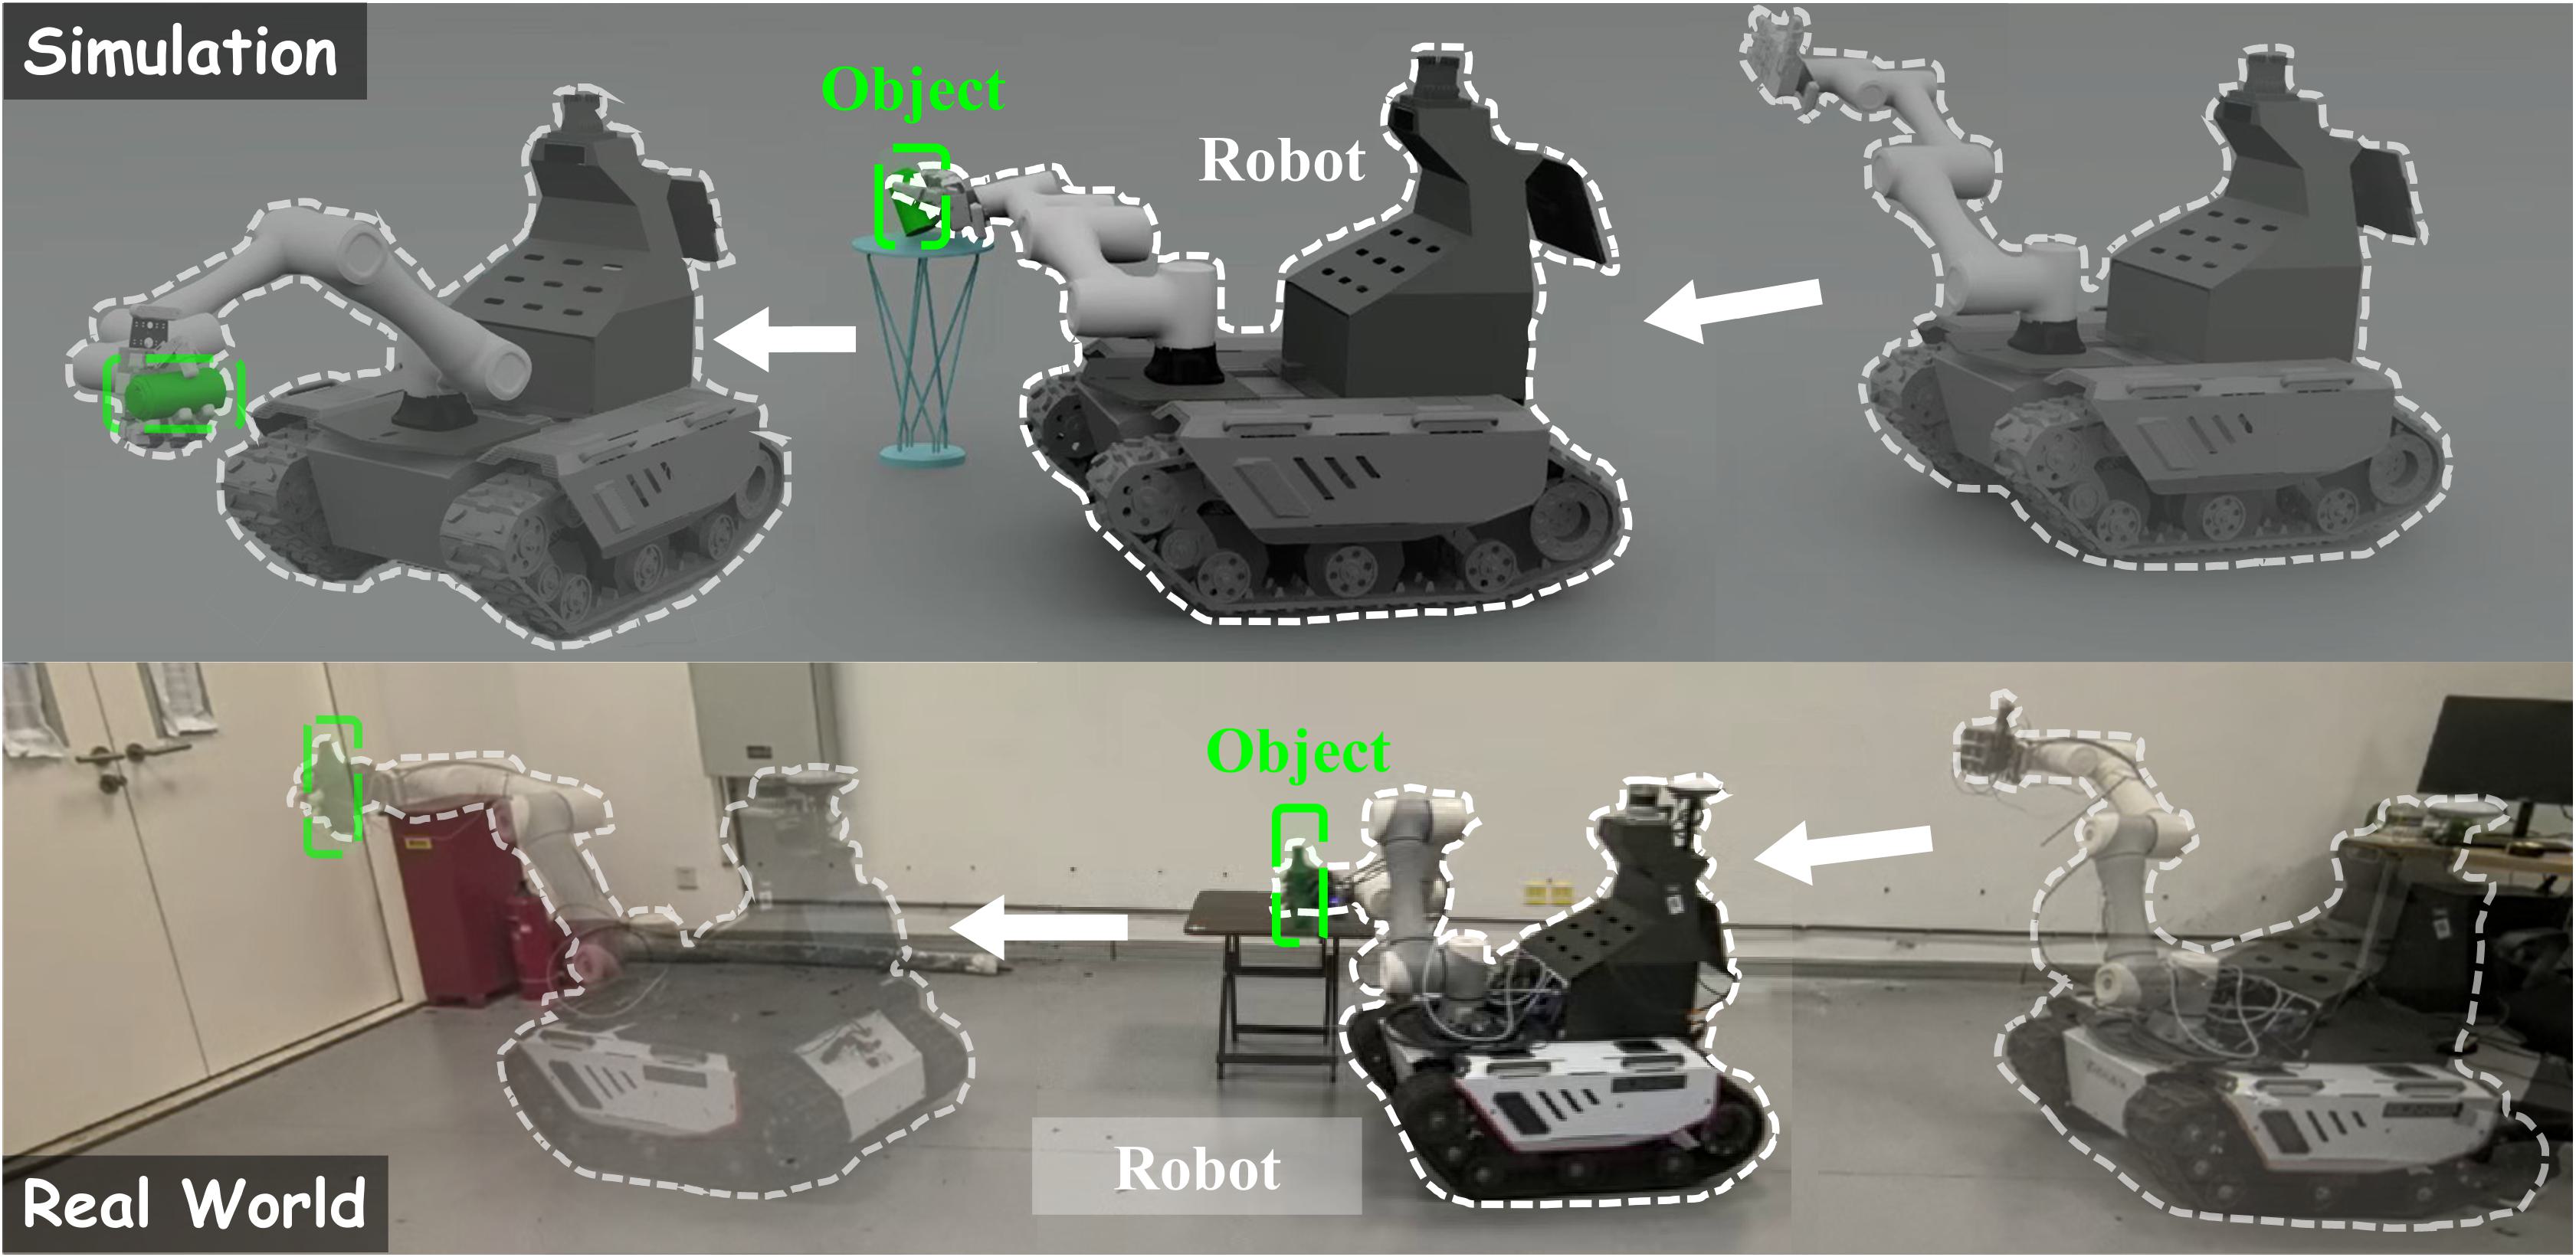
Heng Tao*, Yiming Zhong*, Zemin Yang*, Yuexin Ma†
We introduce FastGrasp, a learning-based framework that combines grasp guidance, whole-body control, and tactile feedback for fast dexterous mobile manipulation. A two-stage reinforcement learning pipeline coordinates the mobile base, arm, and hand, enabling robust grasping in simulation and the real world.
PDF Project page Github
DexH2R: A Benchmark for Dynamic Dexterous Grasping in Human-to-Robot Handover
Youzhuo Wang*, Jiayi Ye*, Chuyang Xiao, Yiming Zhong, Heng Tao, Hang Yu, Yumeng Liu, Jingyi Yu, Yuexin Ma†
This paper introduces DexH2R, a real-world dataset for human-to-robot handovers featuring dexterous motions, diverse objects, and rich annotations. Using teleoperation, it captures natural human-like behaviors for robotic learning.
PDF Page Github
EvolvingGrasp: Evolutionary Grasp Generation via Efficient Preference Alignment
Yufei Zhu*, Yiming Zhong*, Zemin Yang, Peishan Cong, Jingyi Yu, Xinge Zhu, Yuexin Ma†
This paper introduces EvolvingGrasp, which integrates Handpose-wise Preference Optimization with a Physics-aware Consistency Model to enable efficient evolutionary grasp generation, achieving improved grasp success rates and computational efficiency.
PDF Page Github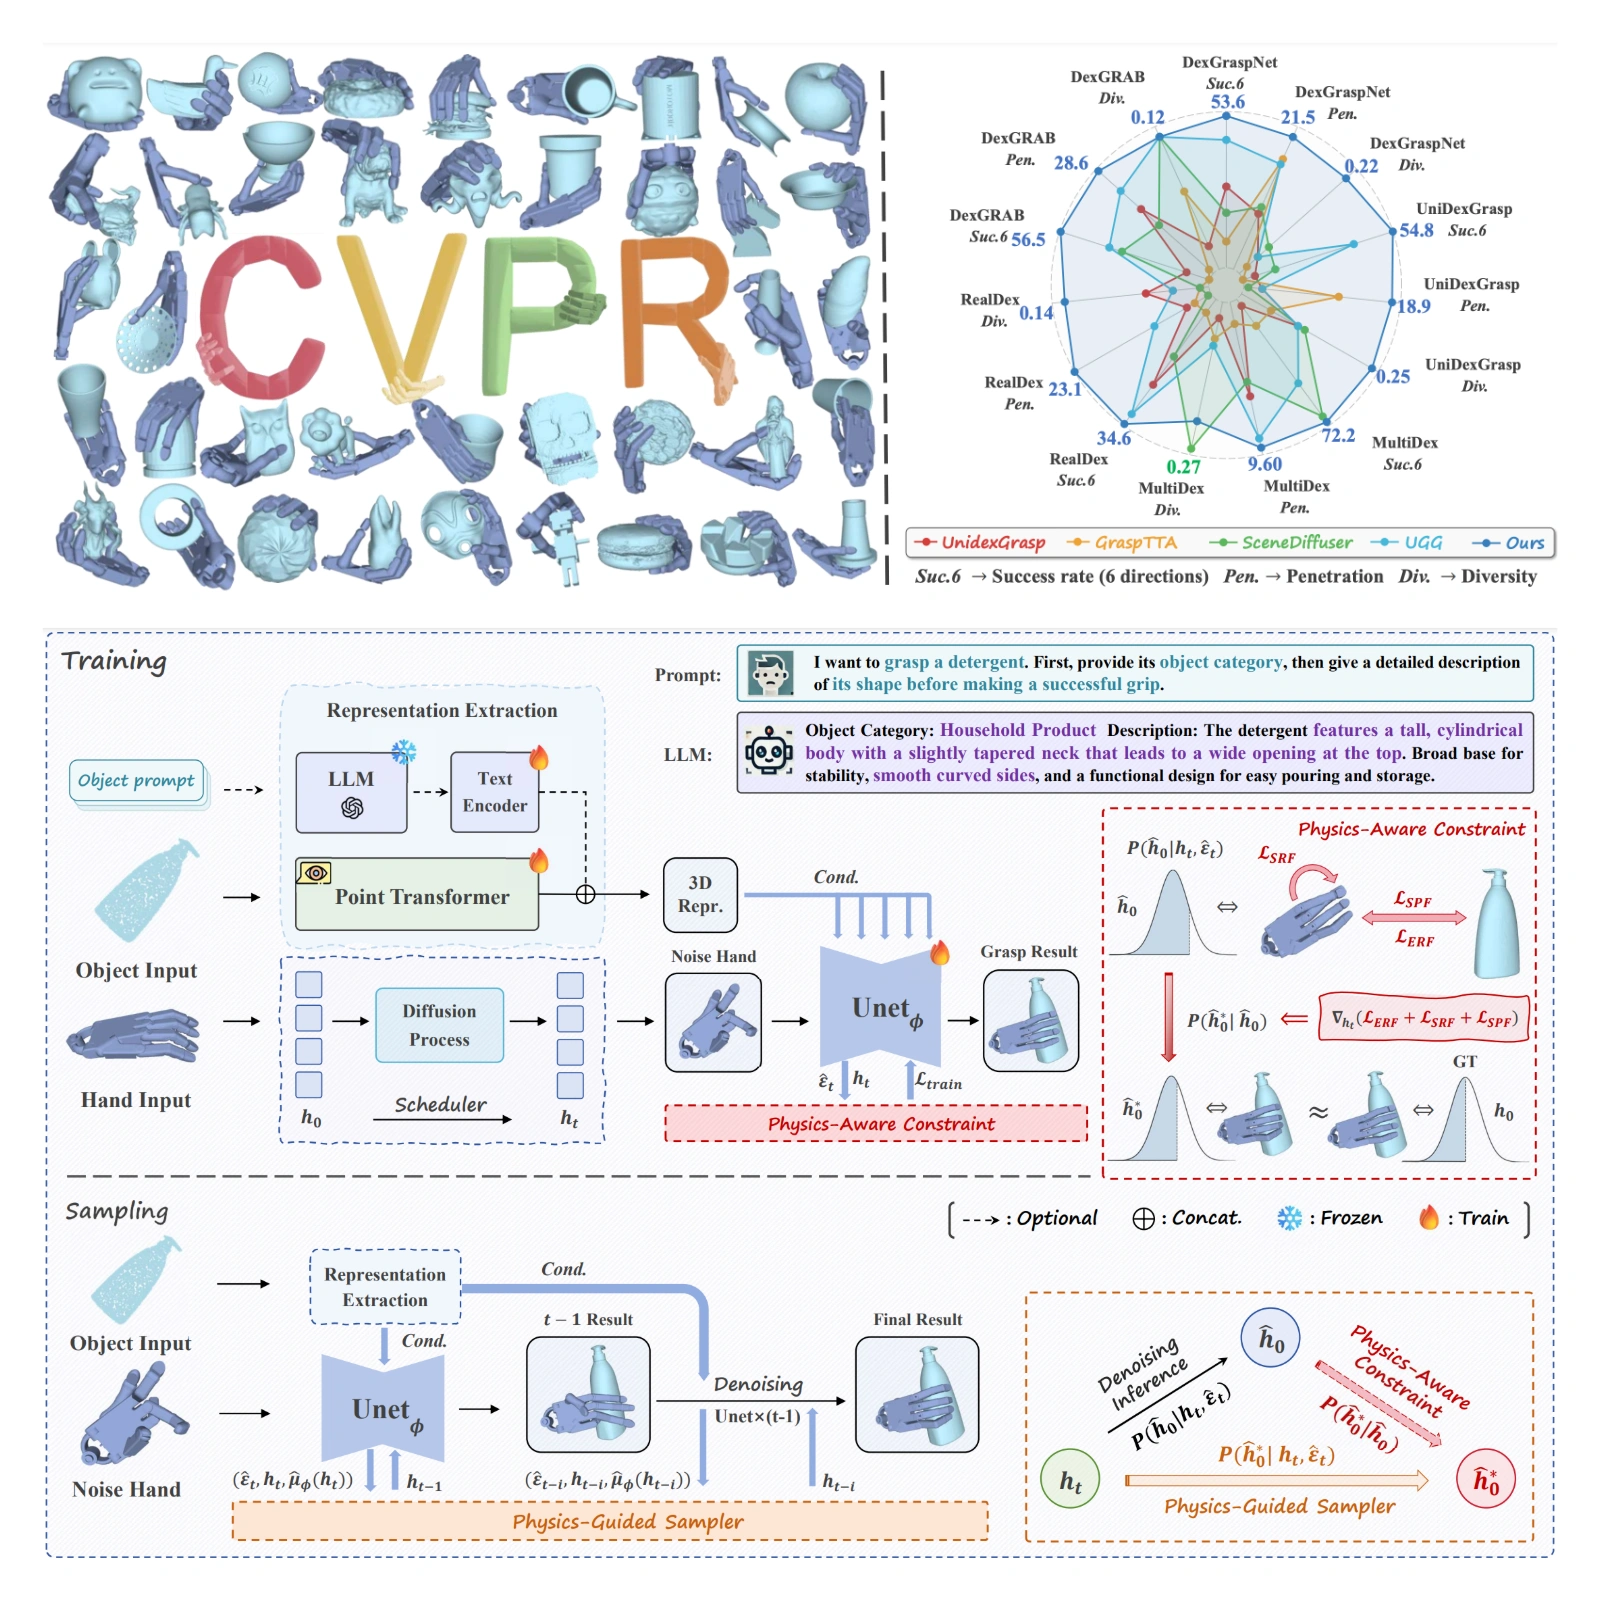
DexGraspAnything: Towards Universal Robotic Dexterous Grasping with Physics Awareness
Yiming Zhong*, Qi Jiang*, Jingyi Yu, Yuexin Ma†
This paper proposes DexGrasp Anything, a diffusion-based method for generating physically plausible grasps with dexterous hands. By integrating physical constraints into both training and sampling, we address high-DOF challenges while synthesizing robust poses for diverse objects. Our 3.4M-grasp dataset (15k+ objects) enables scalable learning, achieving state-of-the-art performance in universal robotic grasping across benchmarks.
PDF Page GithubSpatial Perception & Reasoning
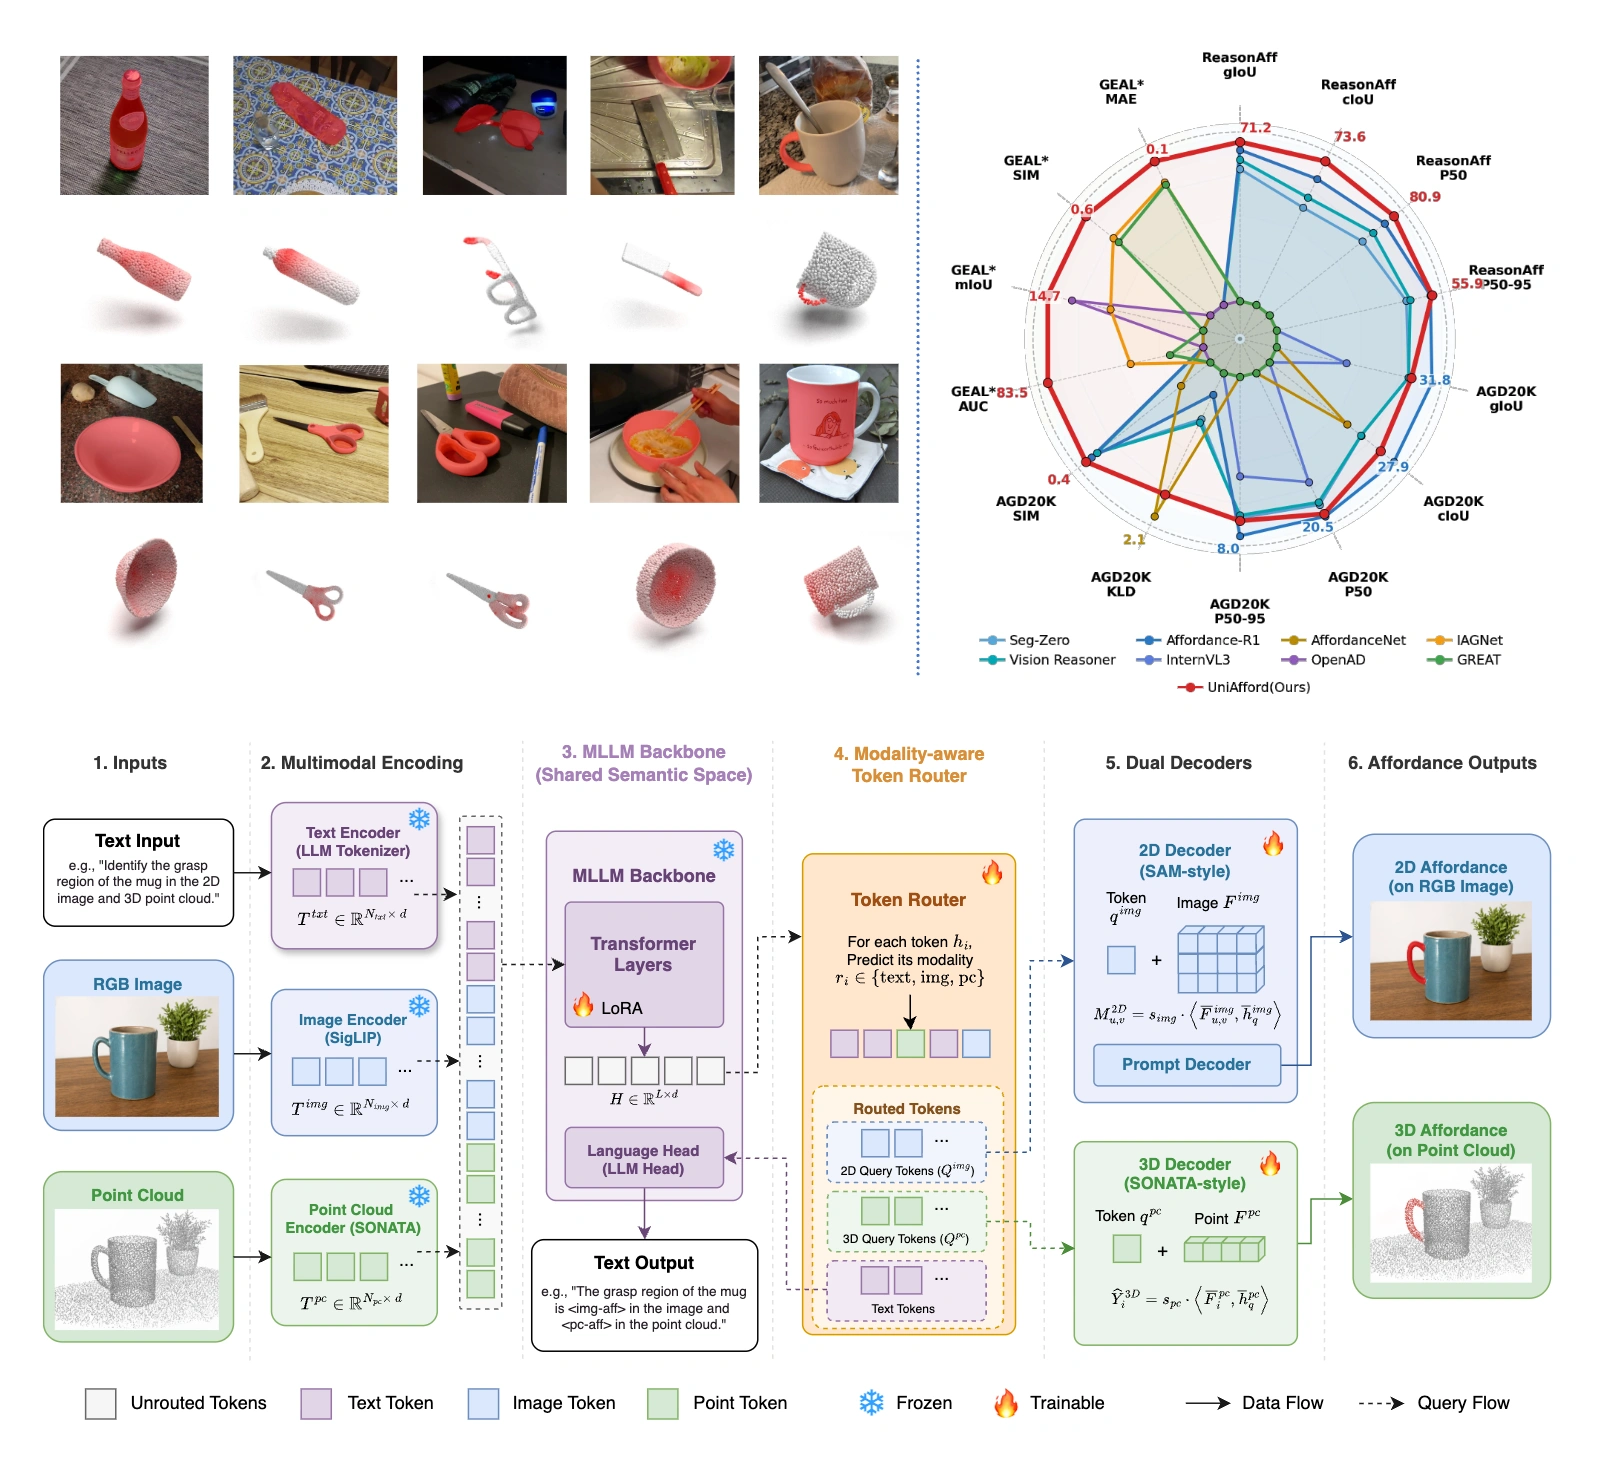
UniAfford: Token-Routed Multitask Learning for Generalizable 2D-3D Affordance Perception
Yuhao Liu, Yiming Zhong‡, Hanqing Wang, Shaocheng Yan, Yuhang Zhang, Wenzhou Lyu, Ziyang Ding, Wei Zhang, Xue Chao, Jin Pan, Yuexin Ma†, Xinge Zhu†
We introduce UniAfford, a unified framework for generalizable 2D-3D affordance perception. A shared multimodal language model uses token-based task routing and modality-specific decoders to learn from pixel-level and point-level supervision, supporting image, point-cloud, and joint multimodal inputs.
Project page Github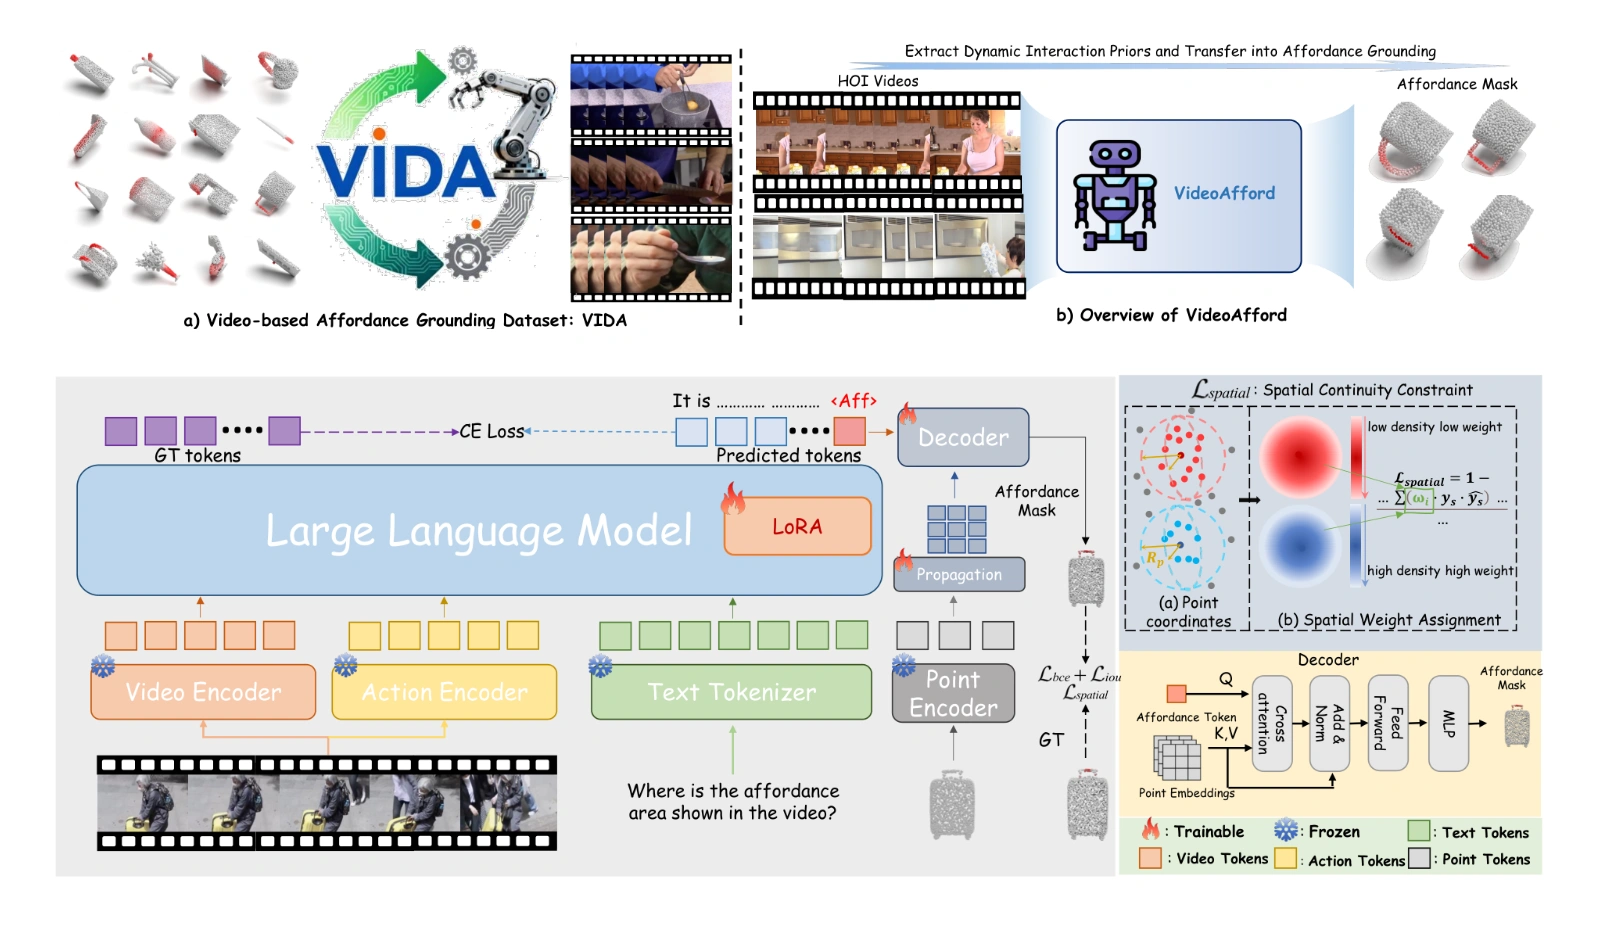
Hanqing Wang, Mingyu Liu, Xiaoyu Chen, Chengwei Ma, Yiming Zhong, Wenti Yin, Yuhao Liu, Zhiqing Cui, Jiahao Yuan, Lu Dai, Zhiyuan Ma†, Hui Xiong†
We introduce VideoAfford and the VIDA dataset to learn 3D affordances from human-object interaction videos. By combining multimodal language models with latent action priors and a spatial-aware loss, VideoAfford enables fine-grained affordance grounding and reasoning with strong open-world generalization.
PDF
Hanqing Wang*, Shaoyang Wang*, Yiming Zhong, Zemin Yang, Jiamin Wang, Zhiqing Cui,Jiahao Yuan, Yifan Han, Mingyu Liu, Yuexin Ma†
We introduce Affordance-R1, which is capable of generating explicit reasoning alongside the final answer. With the help of proposed affordance reasoning reward, it achieves robust zero-shot generalization and exhibits emergent test-time reasoning capabilities.
PDF Page Github🎖 Honors and Awards
- 05/2023 Mathematical Contest In Modeling (MCM) Finalist Prize (Top 1%)
- 09/2022 China Undergraduate Mathematical Contest in Modeling (CUMCM) National First Prize (Top 0.5%)
- 10/2025 National Scholarship for 2024–2025 Outstanding Academic Performance (Top 1%)
- 11/2025 Huahong Scholarship (Top 1%)
- 11/2025 Outstanding Master Student (Top 5%)
📖 Educations
ShanghaiTech University
September 2024 - Now
Major: Master in Computer Science
Shandong University
September 2020 - July 2024
Major: B.S. in Statistics; Second Major: Computer Science
🎨 Hobbies
🚴🏻♂️ Cycling, 🎮 FPS Games, 🏀 Basketball